

Backend.AI Confidential AI:
Your Model and User Data,
Hidden from the Host
Confidential computing design, Intel integration, and roadmap

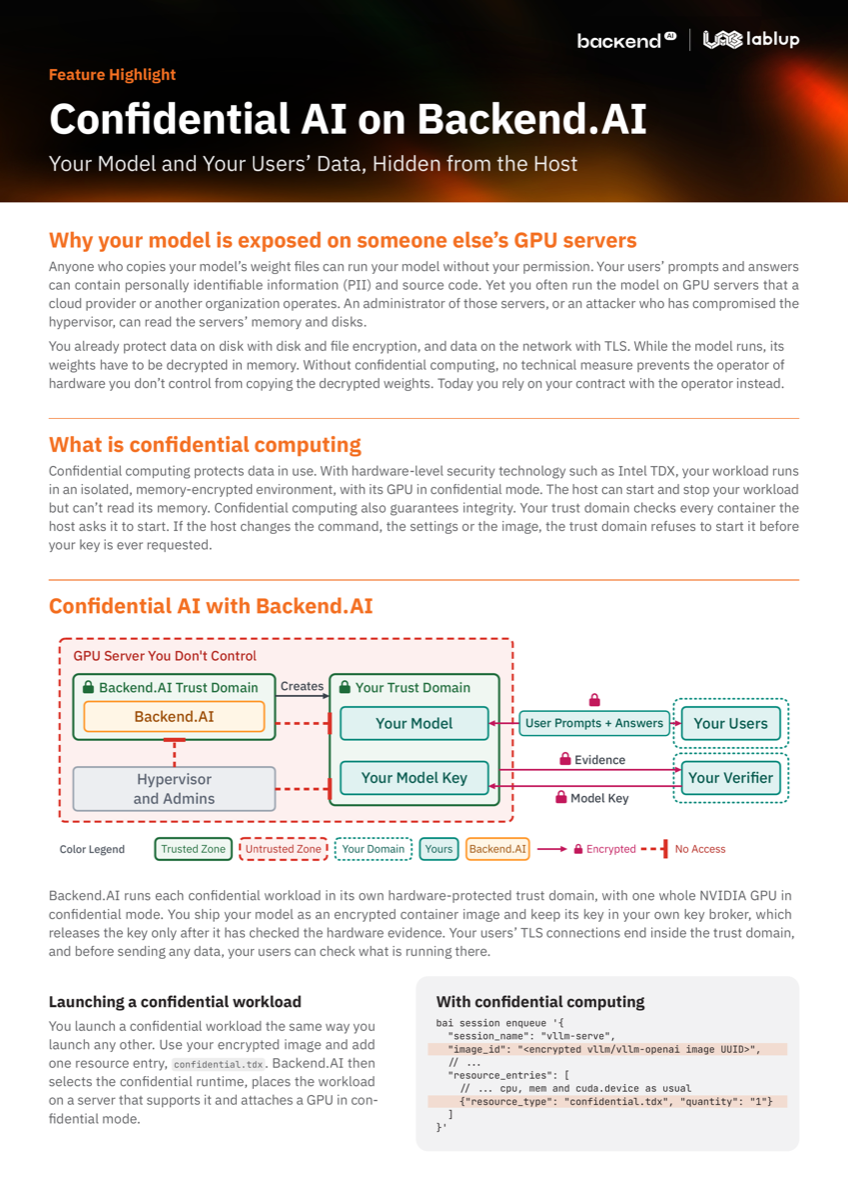
Confidential AI on Backend.AI runs each confidential workload in a hardware-protected trust domain, so neither the GPU server's administrators nor its hypervisor can read your model weights or your users' prompts and answers. Your own key broker releases the model key only after it has checked the hardware evidence. Learn how Backend.AI deploys confidential model services on the open-source Confidential Containers stack without a Kubernetes cluster, how it works with Intel Trust Authority, and what is on the roadmap.
Who Is This Document For?
This document is written for security teams and AI platform teams that serve their own models on GPU servers operated by a cloud provider or another organization and are evaluating how to protect model weights and user data there. It is especially suited to organizations that run model services handling prompts with personally identifiable information (PII) or source code on external GPU infrastructure. Organizations that want to replace contractual assurances from the operator with hardware-based attestation, or that need model keys managed through an existing enterprise key manager or hardware security module (HSM), can also evaluate it.
Backend.AI uses the standard Confidential Containers (CoCo) components, including Kata Containers, the CoCo guest components and Trustee as the key broker. Its own scheduler and node agent place confidential workloads directly on bare-metal servers, so you deploy a confidential model the same way as any other Backend.AI model service. The current scope is a single node with one whole NVIDIA GPU per confidential workload, at sites with internet access. The roadmap includes multi-GPU confidential serving, confidential sessions across several nodes, confidential storage, and AMD SEV-SNP support. See the full document for a comparison of a self-hosted verifier with Intel Trust Authority and an example of launching a confidential workload.
Related Services

Backend.AI is a vendor-agnostic accelerated workload hosting platform based on our own home-grown orchestration and job scheduler, running on top of either cloud or on-premises (air-gapped) clusters.
Explore service →